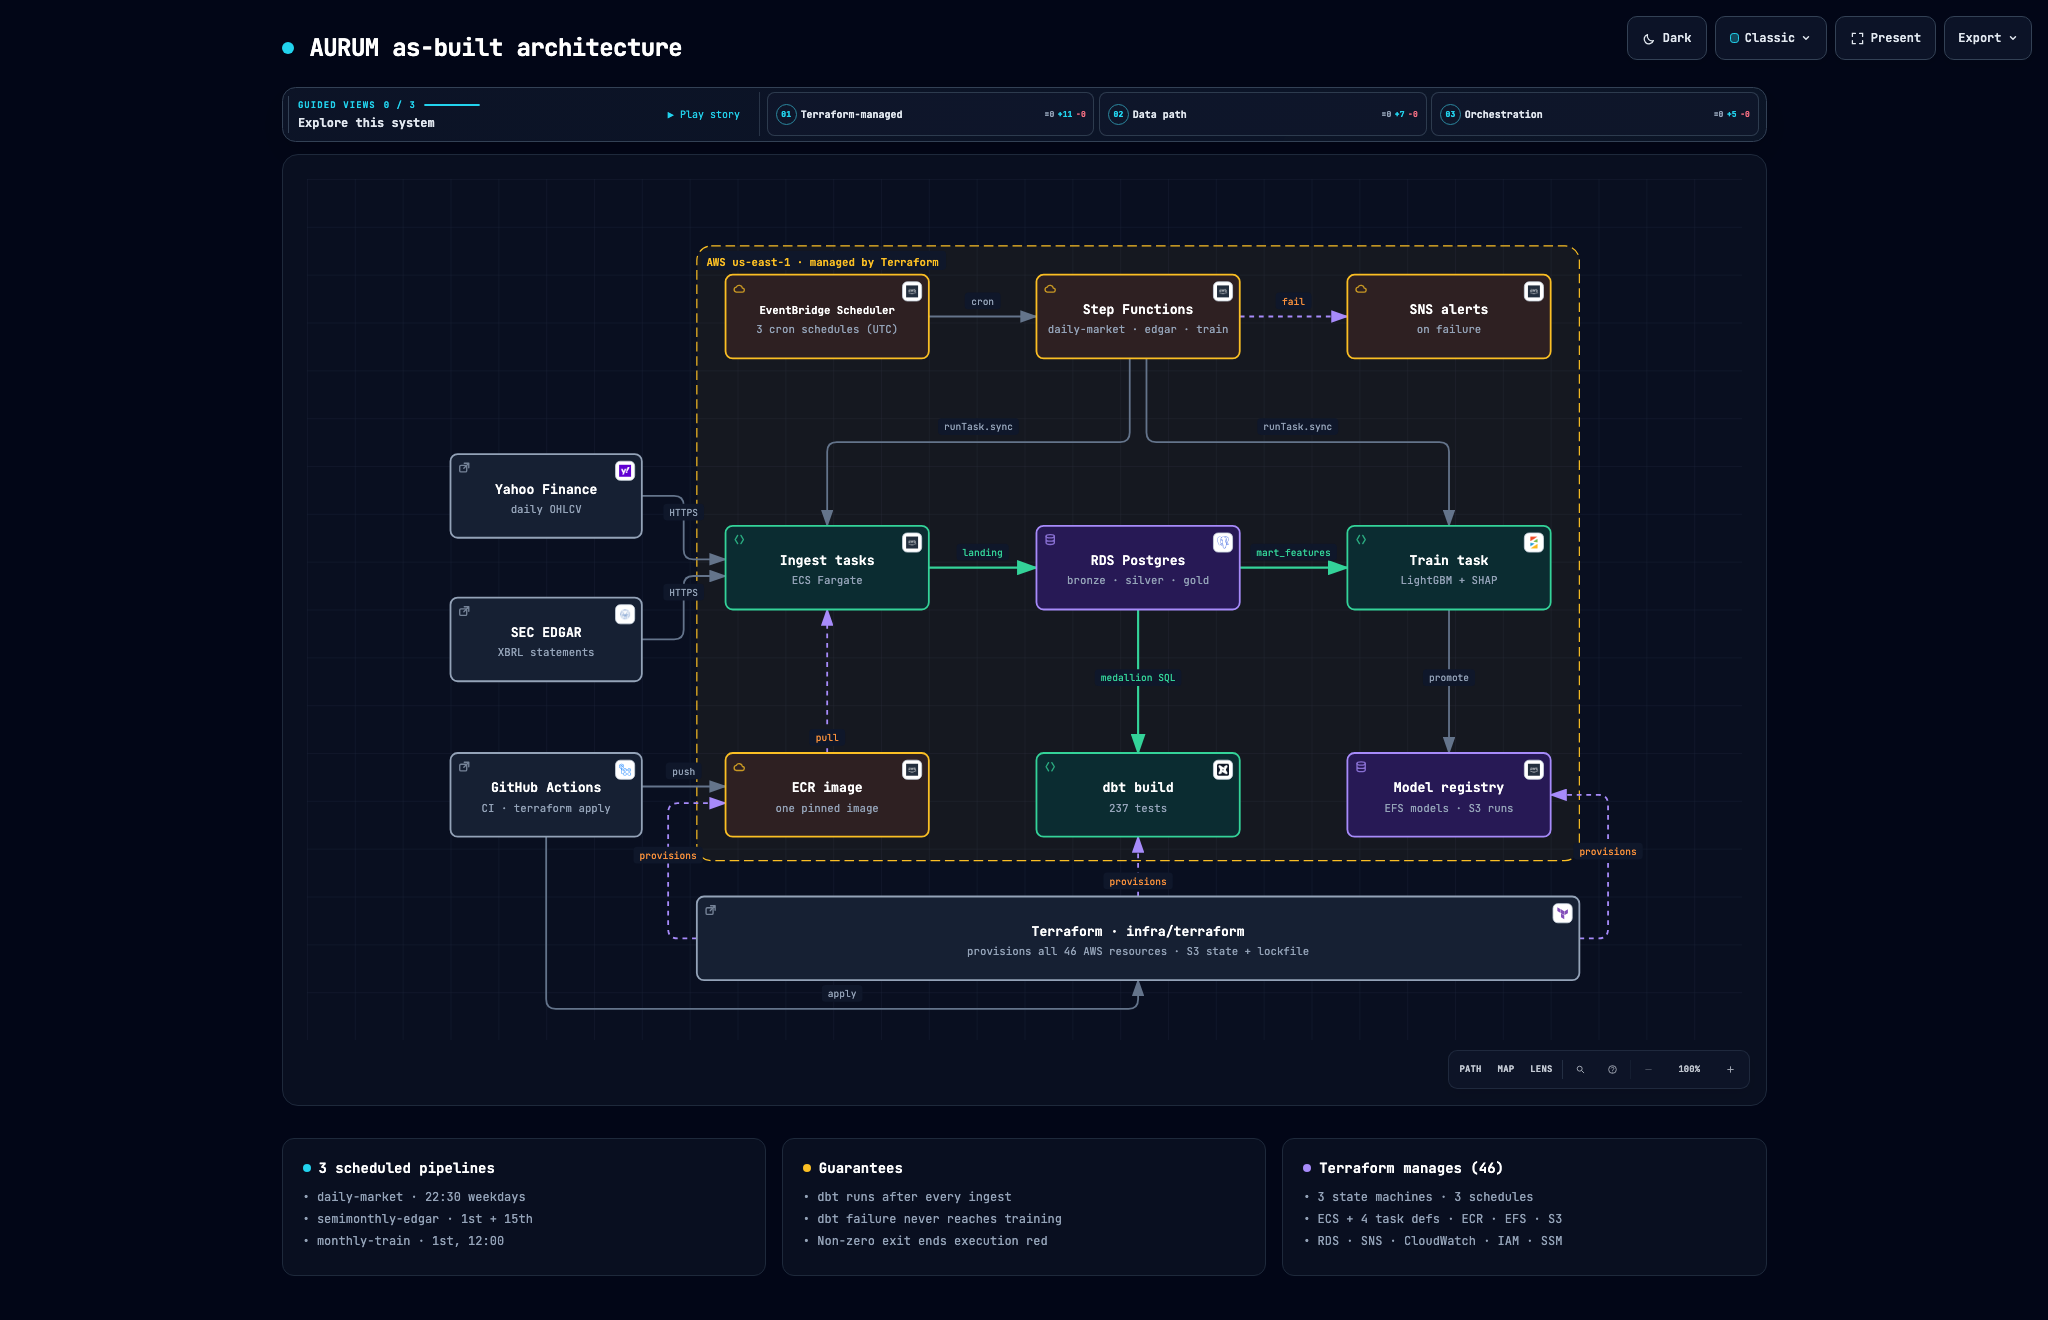
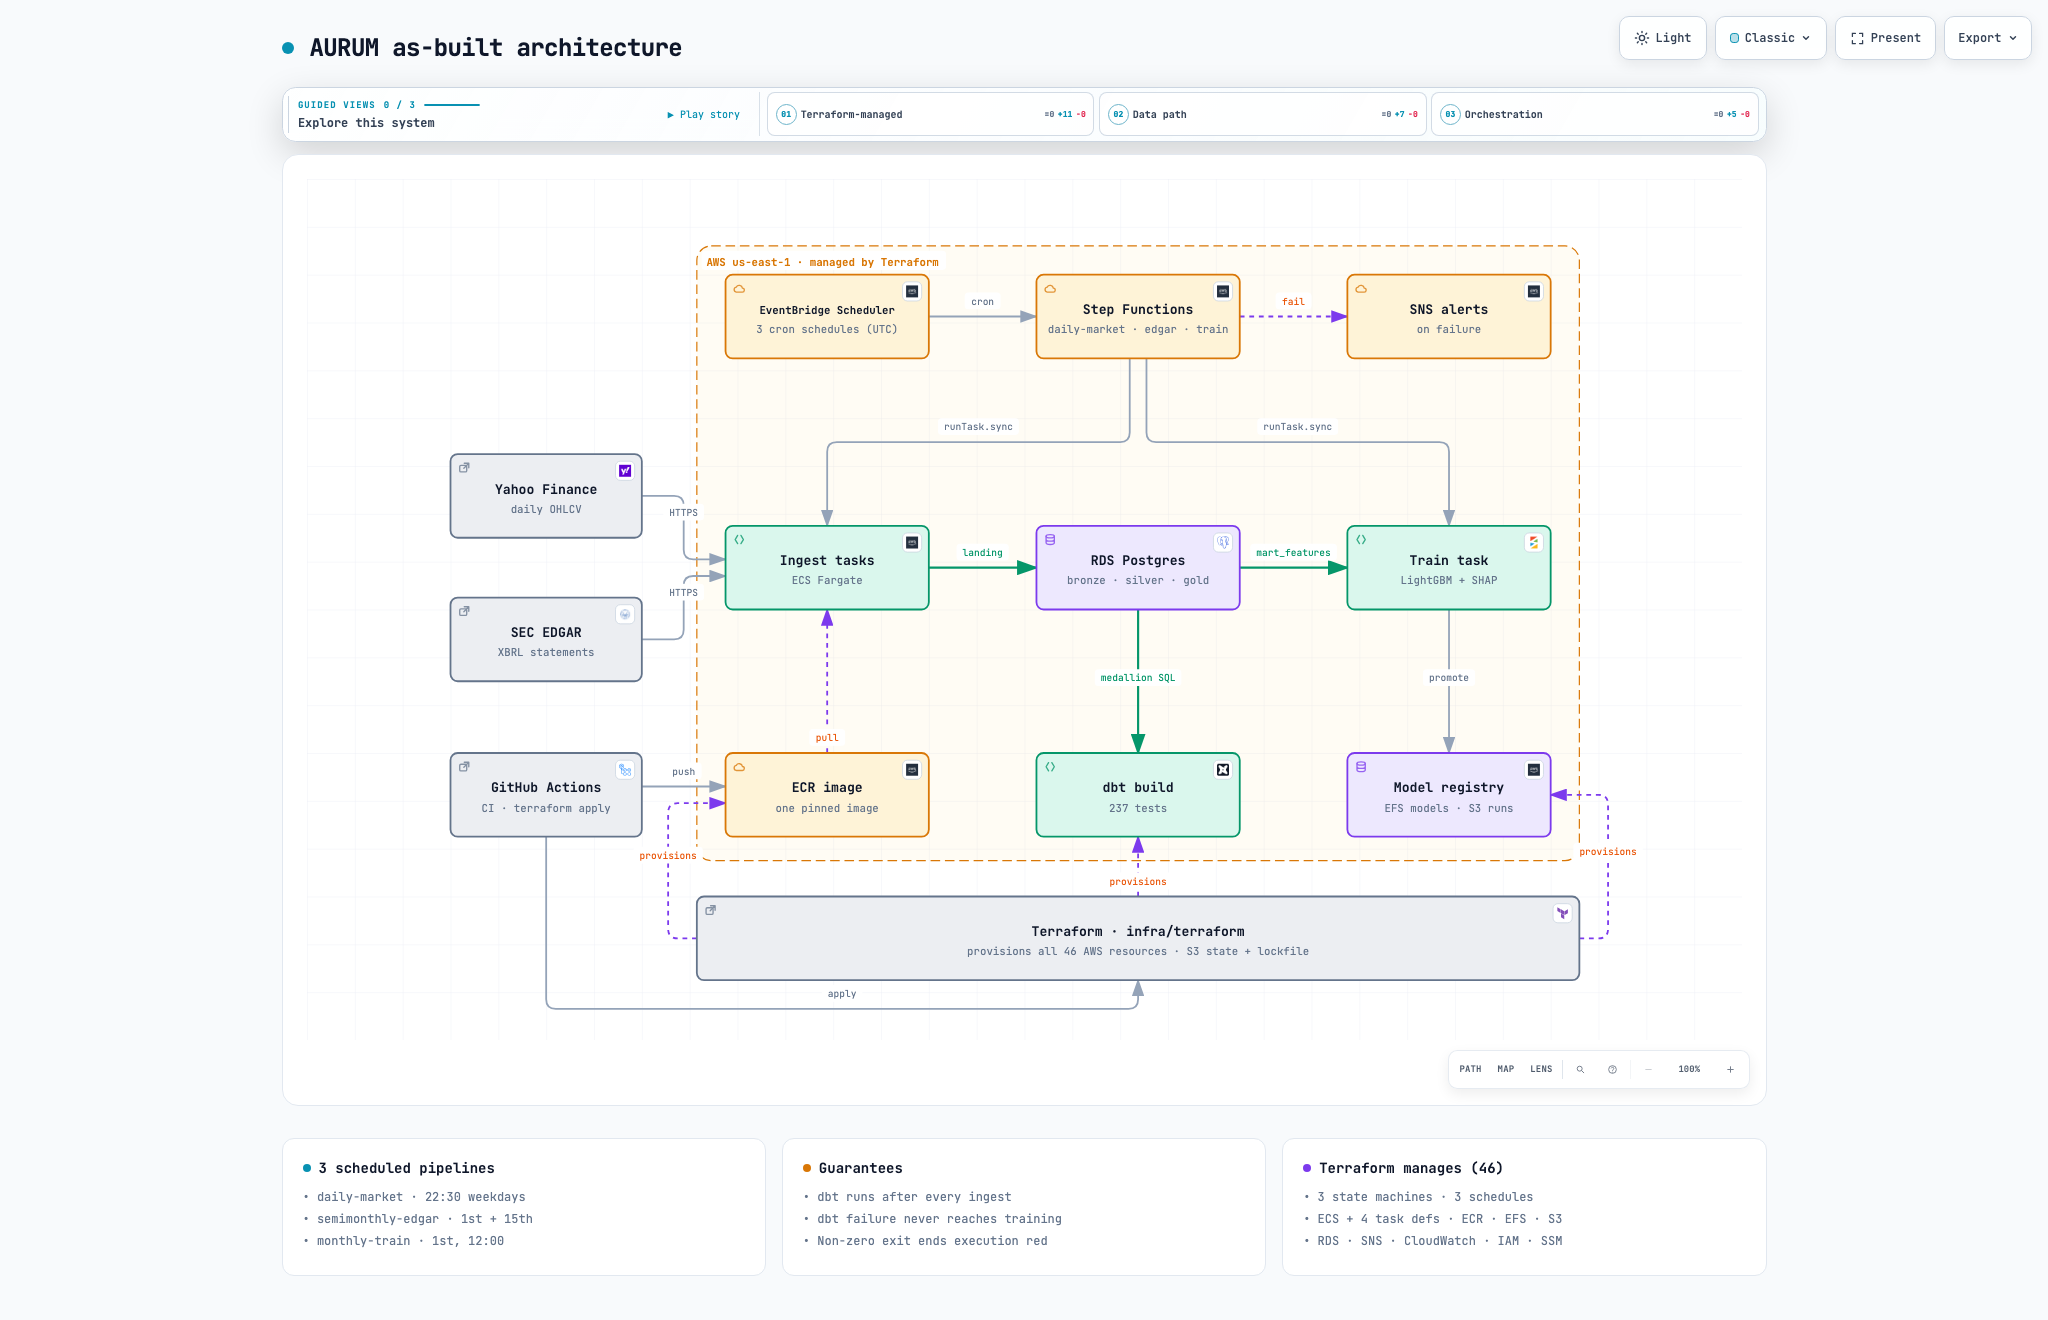
FlagshipAnalytics & Unified Research for Market
AURUM solo.
The entire stack an investment data team builds. Built alone.
- S&P 500 symbols
- 503
- Daily history to today
- 2000→
- Feature rows in gold
- ~2.9M
Rohit Kumar
Data Engineer · Moody's Ratings
I design ingestion frameworks, lakehouses and data APIs that stay correct when nobody is watching — and, more and more, the MCP servers and services that hand that data to AI.
4+ years
in data
Moody's Ratings
About
Started in analytics at Axis Bank, moved into engineering to fix data problems at the source. Today I build ingestion frameworks, an Iceberg lakehouse with an MCP server, and the APIs that feed agentic-AI workflows at Moody's.
01/Experience · 4+ years
Analytics at a bank, then data platforms at a ratings agency — making data trustworthy enough to act on.
Apr 2025 — Present · Bengaluru
−60% infra cost
Built and led deployments of the AIDE ingestion framework — 80+ feeds from 10+ heterogeneous sources (JDBC, APIs, S3) — and cut deployment time by 75%.
100+ TB governed
Operationalised data quality and governance with Great Expectations across 95%+ of feeds, with CloudWatch dashboards giving stakeholders one view of data health and faster debugging.
−95% index buildData × AI
Improved DB indexing for unstructured data on pgvector, enabling fast similarity search and cutting index build time by ~95% for agentic-AI workloads.
−50% data prepData × AI
Led development of an Apache Iceberg lakehouse with ACID transactions and lineage for 30+ data scientists, and built an MCP server for fast data access and exploration.
30K+ req/dayData × AI
Architected and shipped two Spring Boot / MongoDB services delivering relevance-scored news and issuer sentiment to an analyst workbench and agentic-AI workflows — manual triage down 90% at p95 < 20 ms.
02/Recognition & learning
National Institute of Technology, Tiruchirappalli
M.Tech — Energy Engineering · 2022
03/Selected work
Personal builds that go deeper than any one job allows.
The entire stack an investment data team builds. Built alone.
Case studies
swipe →Iceberg Lakehouse POC2026
A personal deep-dive into the open-table-format pattern I use at work: Apache Iceberg tables on S3, registered in Glue and queried through Athena, with a tested dbt layer on top.
Realtime Voting System2024
A streaming aggregation system that processes live voting events and surfaces real-time counts to a dashboard.
Analytics API2024
A lightweight serving layer that exposes time-series data from TimescaleDB to downstream consumers through a clean API.
WhatsApp Chat Analyzer2023
A deployed app that turns exported WhatsApp chats into interactive activity, word and sentiment insights.
04/Toolbox
Grouped the way data moves: in, through, stored, shipped — and handed to a model.
05/Contact
Open to conversations about data platforms, lakehouses, and data-for-AI work.