Reddit Sentiment ETL
How do data communities on Reddit actually feel? A daily pipeline that keeps score.
I wanted a daily read on the mood of r/python, r/dataengineering, r/data and r/career. The pipeline pulls new posts, keeps the raw copy, scores every post with VADER inside Spark, and serves an analytics table to Power BI — orchestrated end to end by Airflow with retries.
Impact
- across 4 subreddits
- Posts scored
- 3,395
- with retries and a 2-minute back-off
- Airflow tasks, daily
- 4
- VADER compound > 0.5
- Positive posts
- 70.7%
- on a −1 to 1 scale
- Overall sentiment
- 0.60
01/Architecture
How the pieces fit.
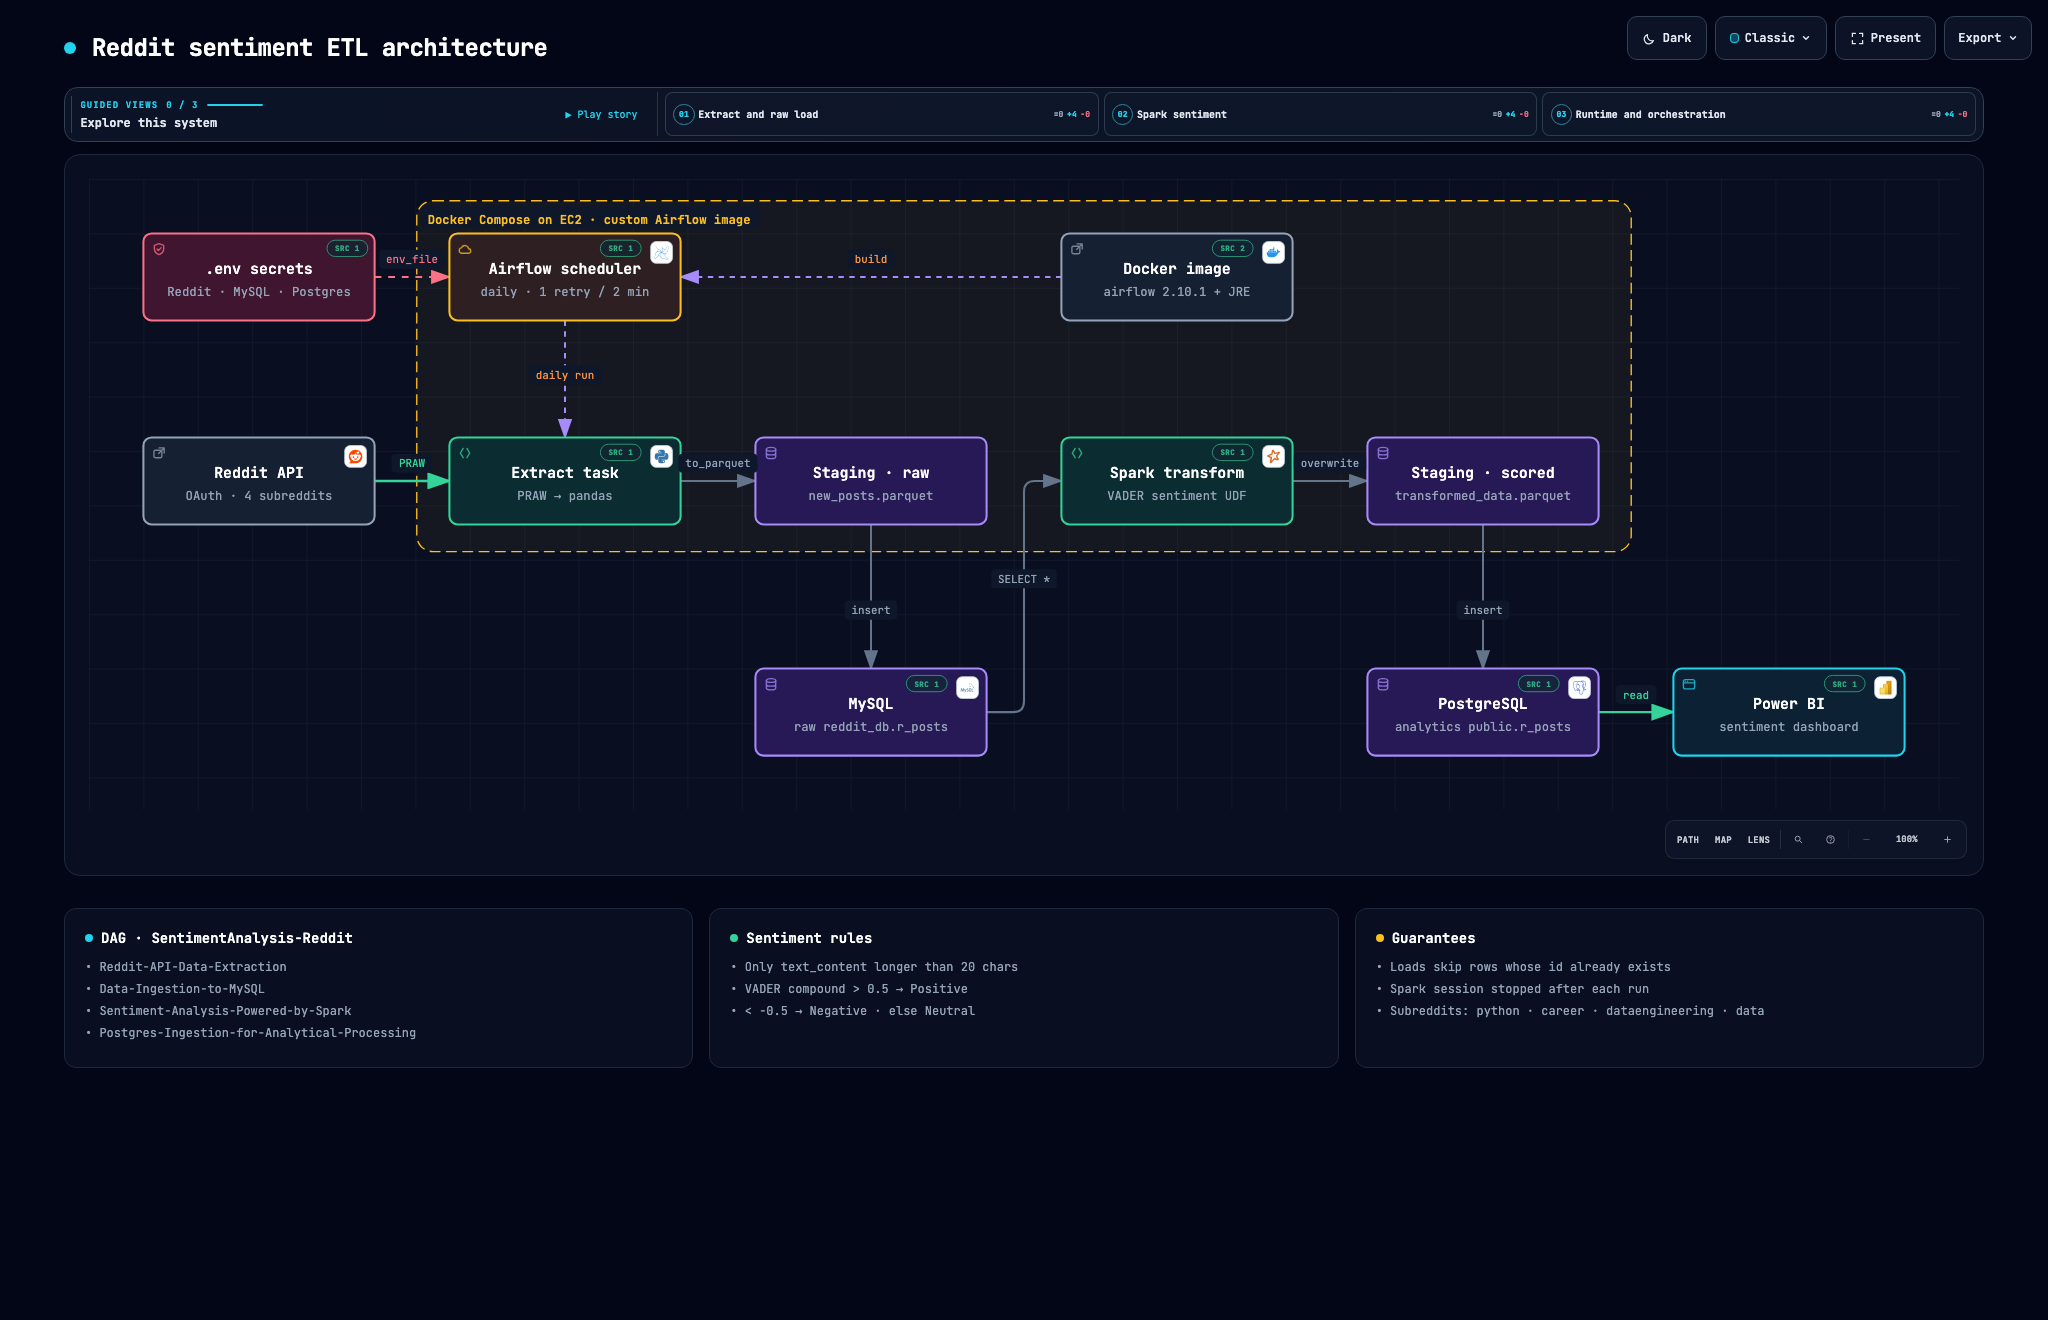
Airflow drives extract → MySQL raw → Spark sentiment → PostgreSQL, which feeds the Power BI dashboard.
02/By the numbers
What the data says.
Average sentiment by subreddit
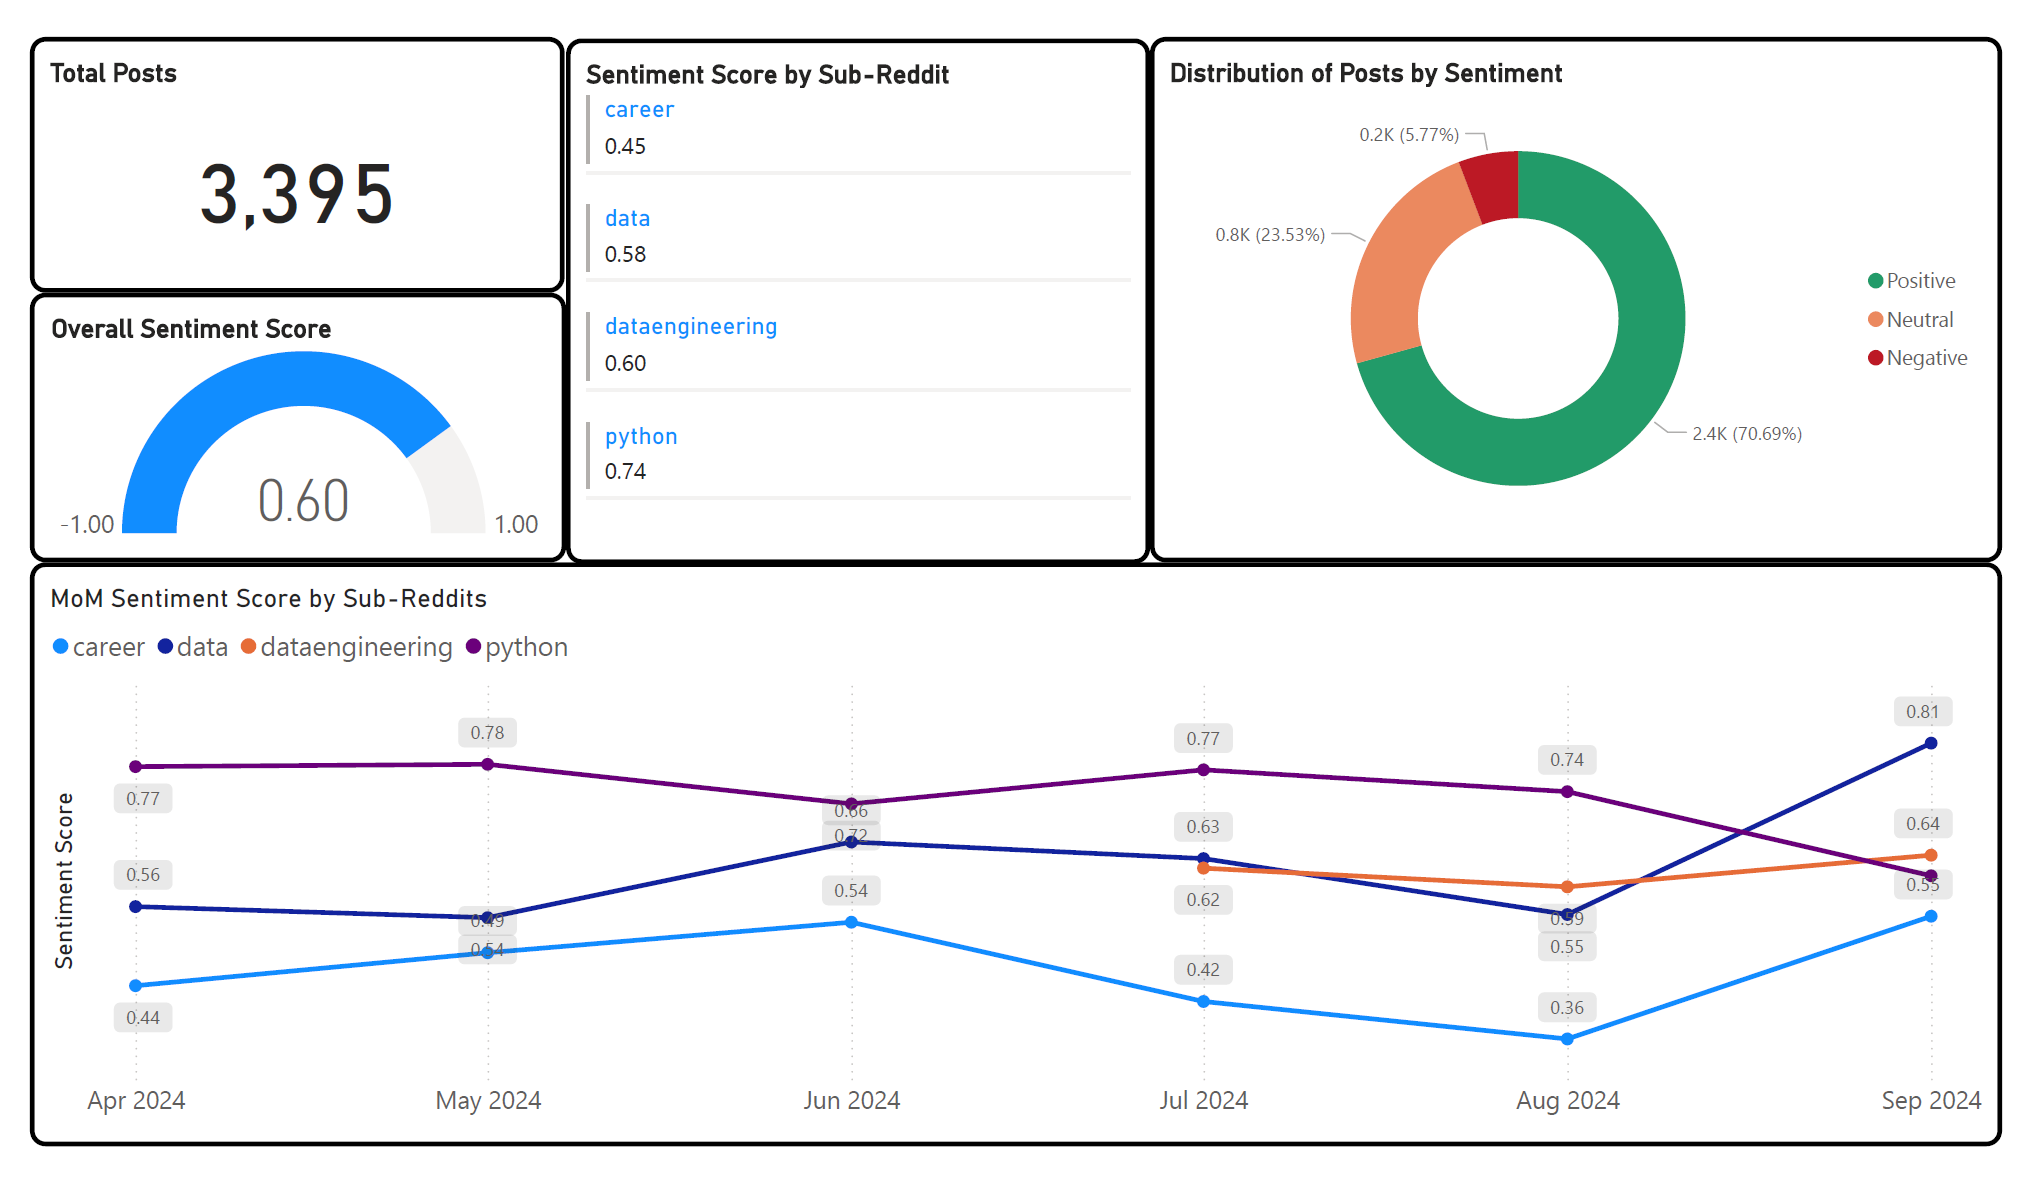
Mean VADER compound score, −1 to 1. r/python is the happiest place in data.
- r/python0.74
- r/dataengineering0.60
- r/data0.58
- r/career0.45
Sentiment distribution
3,395 posts, thresholded at ±0.5.
- Positive2,400 · 70.7%
- Neutral799 · 23.5%
- Negative196 · 5.8%
03/How it works
4 stages, each with a job.
stage 01
Extract
- 01PRAW pulls new posts from four subreddits into a parquet staging file.
- 02Title, body, author, score, comments, upvote ratio and timestamps are captured per post.
04/Evidence
Straight from the repo.
Power BI dashboard
Totals, per-subreddit sentiment and month-over-month trend, April–September 2024.
Airflow DAG
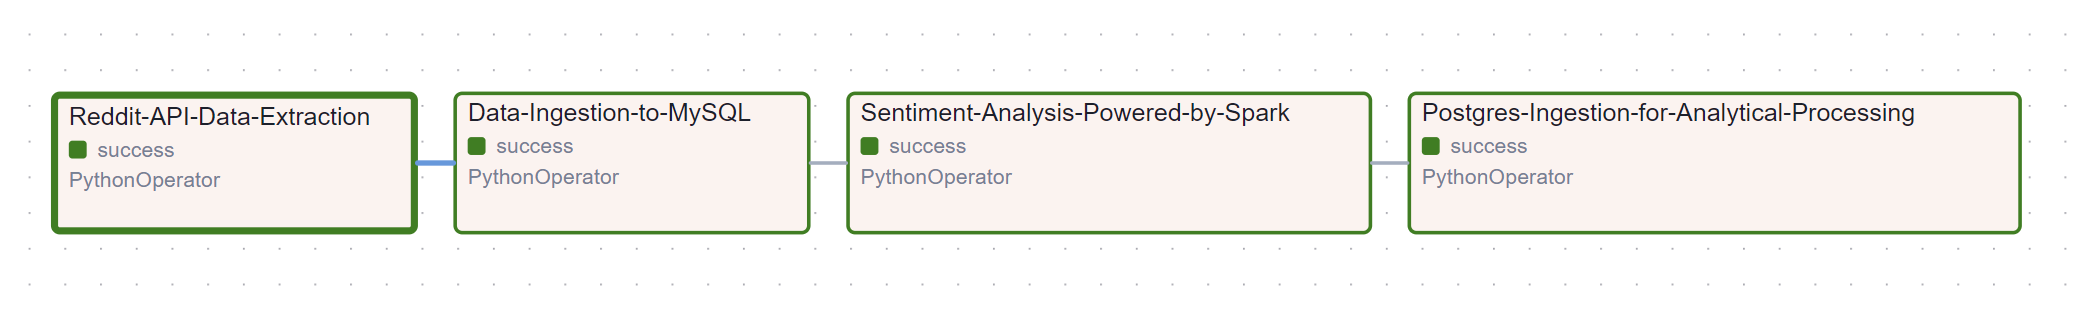
Four PythonOperator tasks, green end to end.
05/Engineering decisions
What I optimised for.
01
Raw and modelled apart
MySQL keeps exactly what Reddit returned; PostgreSQL holds only the scored, analysis-ready shape.
02
Idempotent loads
Every insert checks the post id first, so a retried or re-run DAG converges instead of duplicating.
03
Retries by default
Each task retries once after two minutes — transient API or database hiccups don't page anyone.
04
Containerised Airflow
Docker Compose loads secrets from .env, so the same DAG runs locally and in a container.
06/Stack
Built with.
Next case study
pgvector Index Benchmark
Which Postgres vector index should you actually ship? Measured, not guessed.