TransitFlow Realtime Event Stream
Five live IoT streams, one Spark job, analytics-ready in S3.
A vehicle travelling London → Birmingham emits vehicle, GPS, traffic-camera, weather and emergency events. The goal: move all five streams through Kafka, give each a schema in Spark Structured Streaming, and land them in S3 where Glue, Athena and Redshift can query them — without a manual step in between.
Impact
- vehicle · GPS · traffic · weather · emergency
- Live event streams
- 5
- per stream, on event time
- Late-data watermark
- 2 min
- Glue ETL into Redshift
- Faster reporting
- ~30%
- Dockerised Kafka + Spark
- Less setup time
- 50%
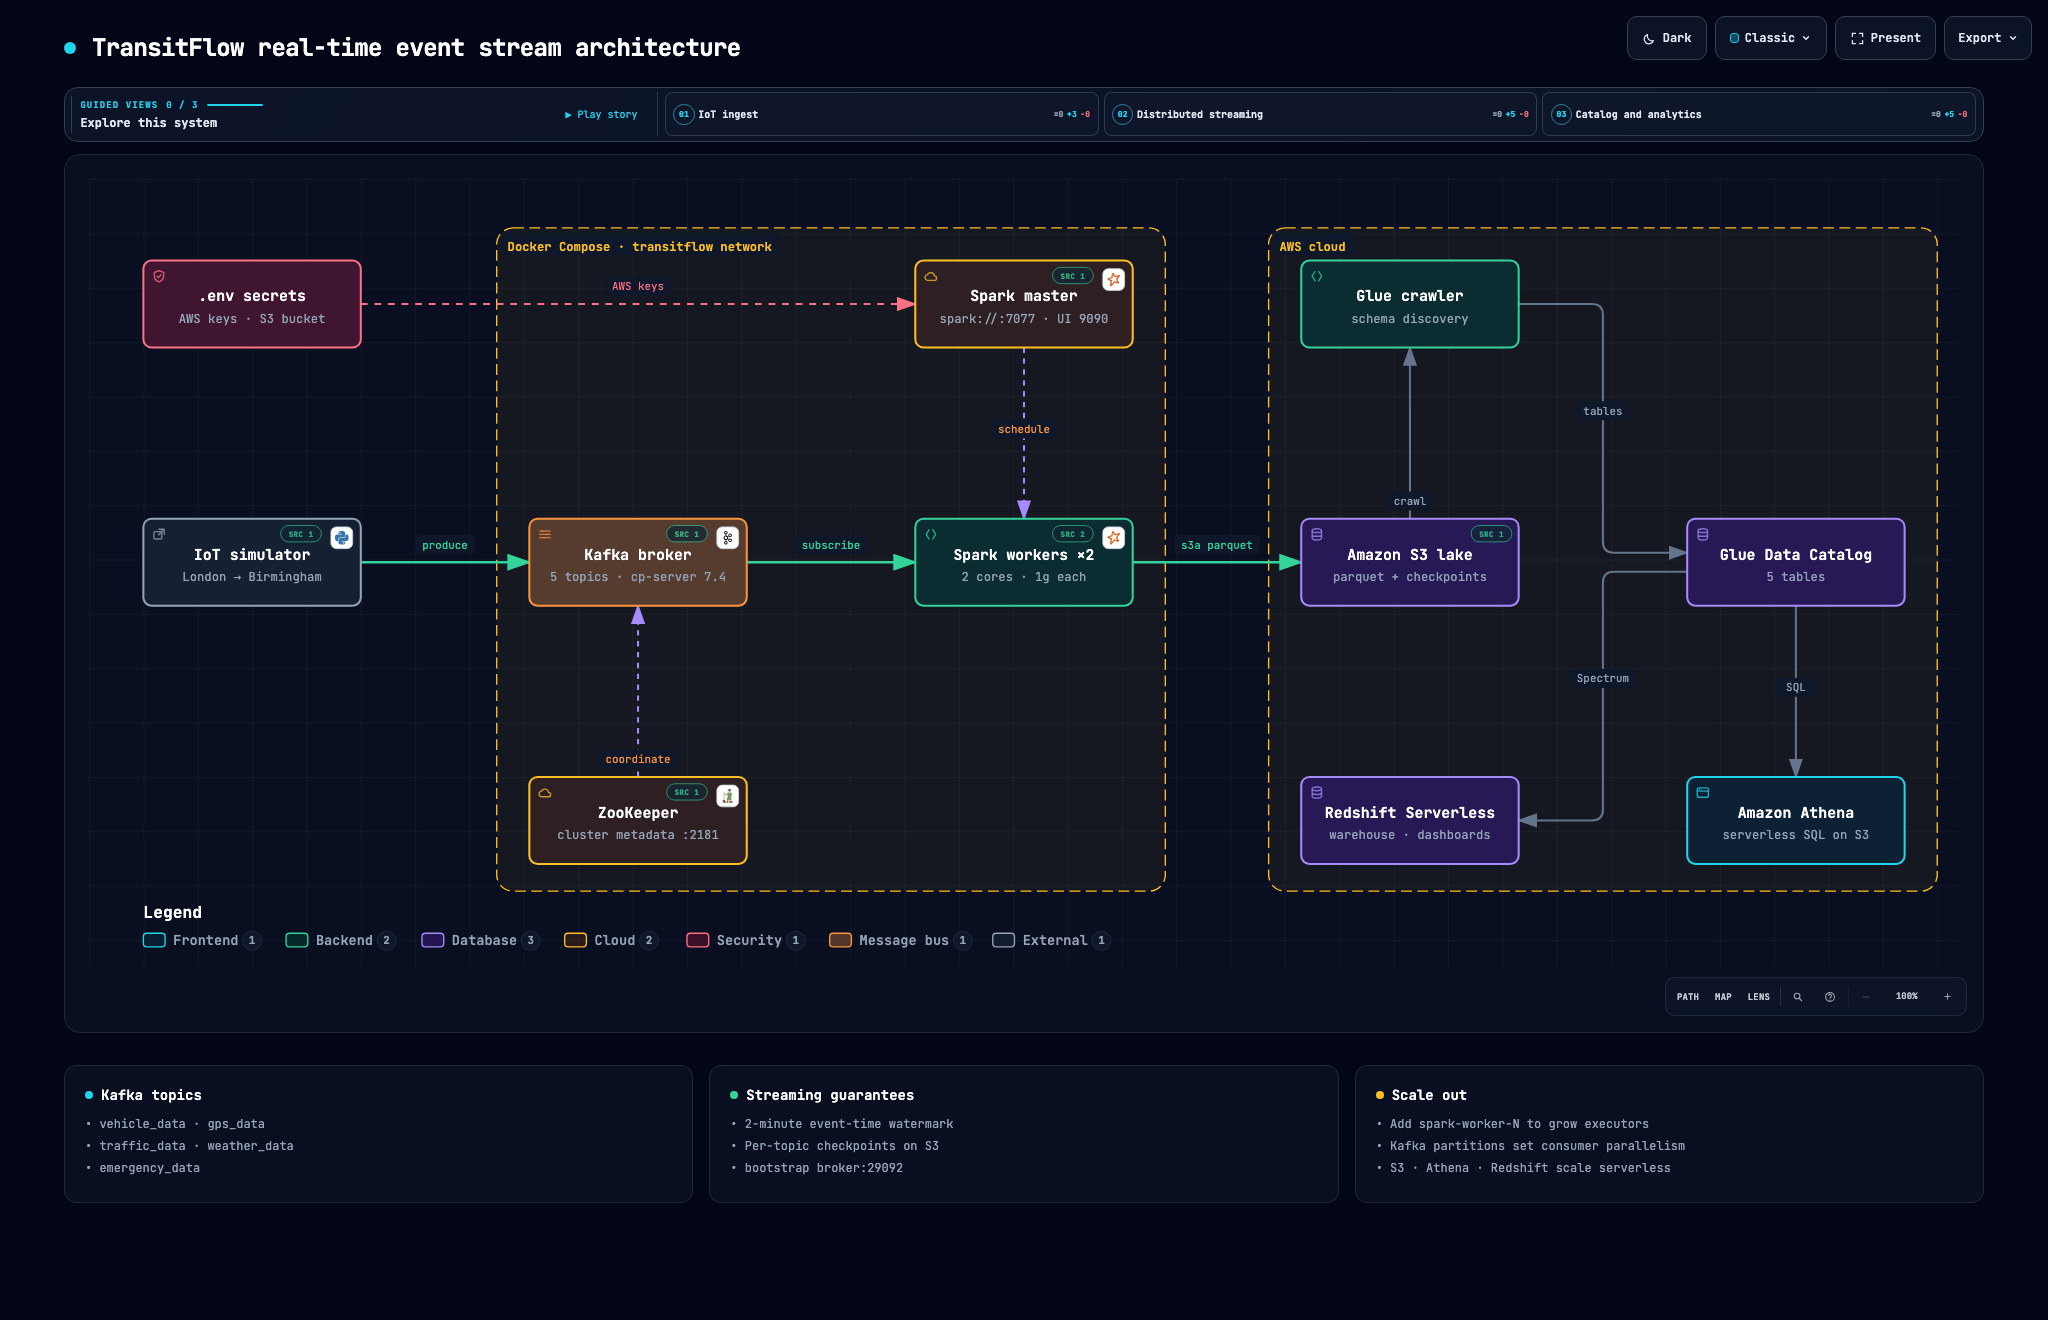
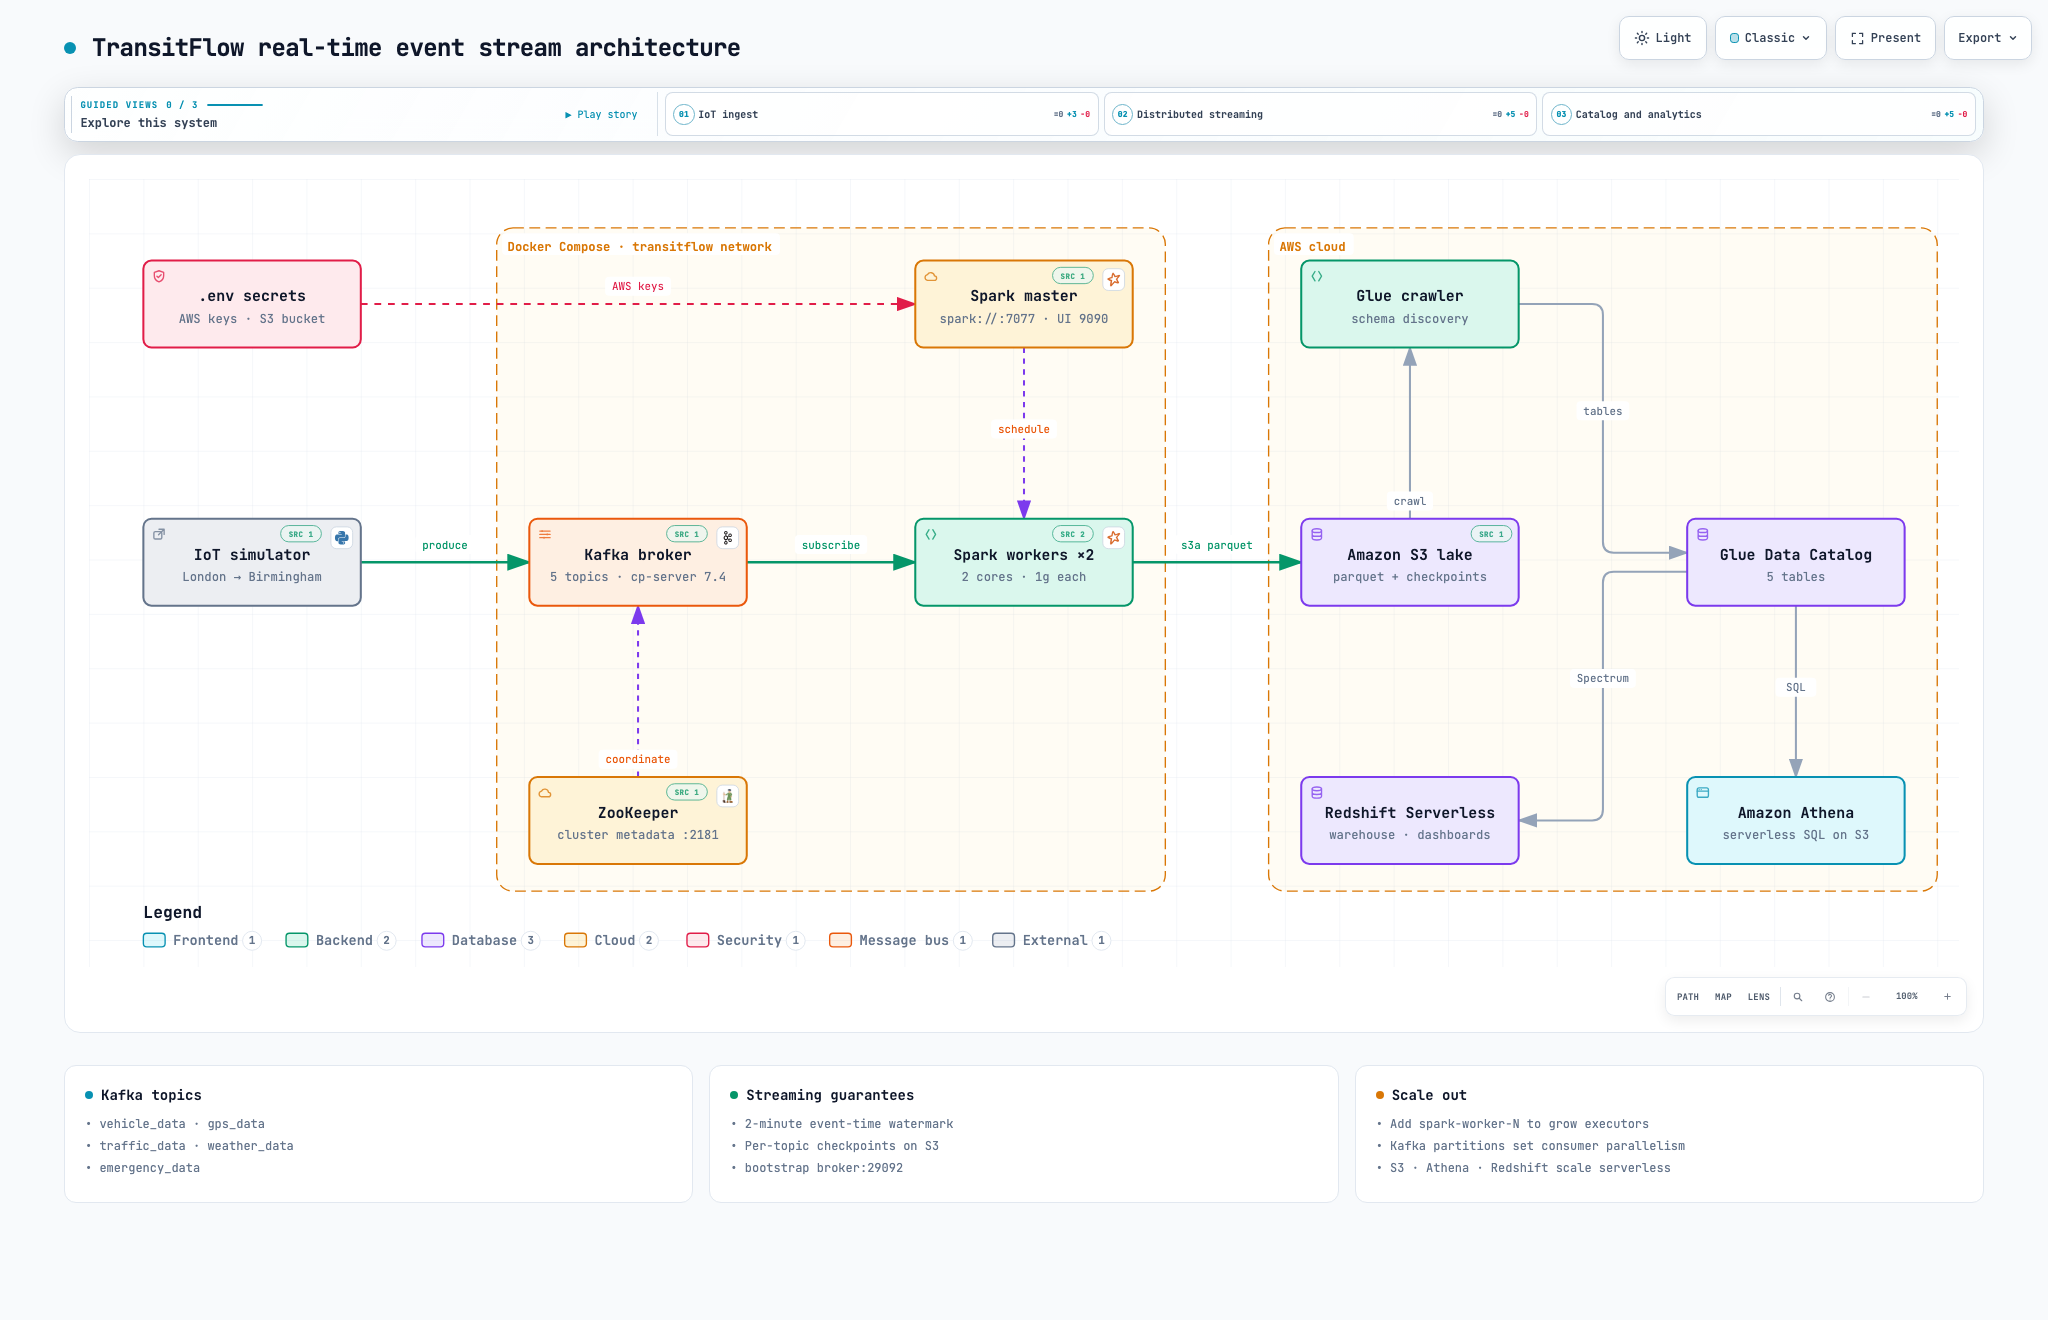
01/Architecture
How the pieces fit.
IoT simulator → Kafka → Spark (master + 2 workers) → S3 lake, catalogued by Glue and queried from Athena and Redshift Serverless.
02/By the numbers
What the data says.
Fields per event stream
Each Kafka topic gets its own explicit Spark schema.
- vehicle_data10 fields
- weather_data10 fields
- emergency_data8 fields
- gps_data6 fields
- traffic_data6 fields
03/How it works
4 stages, each with a job.
stage 01
Simulate
- 01A Python producer moves a vehicle from London to Birmingham in 100 steps with realistic jitter.
- 02Each step emits five correlated events sharing device id, timestamp and location.
- 03Events are keyed by id and serialised to JSON with a delivery callback per message.
04/Engineering decisions
What I optimised for.
01
Topic per event type
Streams evolve independently — a new weather field never forces a change to the vehicle pipeline.
02
Schemas at the edge
Explicit Spark schemas turn loose JSON into typed columns before anything lands in the lake.
03
Checkpointed sinks
Each query has its own S3 checkpoint, so a restarted job resumes from its last committed offset.
04
Local first
Kafka, ZooKeeper and Spark come up with one docker-compose command — the whole stream is reproducible on a laptop.
05/Stack
Built with.
Next case study
Reddit Sentiment ETL
How do data communities on Reddit actually feel? A daily pipeline that keeps score.