AURUM
The entire stack an investment data team builds. Built alone.
Stock research needs clean, point-in-time data before any model is worth trusting. I wanted to build every layer myself — ingestion, warehouse, features, model, and the cloud infrastructure that runs it — to production standards, using only free data sources.
- S&P 500 symbols
- 503
- Daily history to today
- 2000→
- Feature rows in gold
- ~2.9M
- dbt tests per build
- 237
- Step Functions workflows
- 3
- Manual steps
- 0
01/Architecture
One system, as built.
Interactive diagram of what runs today — switch between the Terraform, data-path and orchestration views inside the frame.
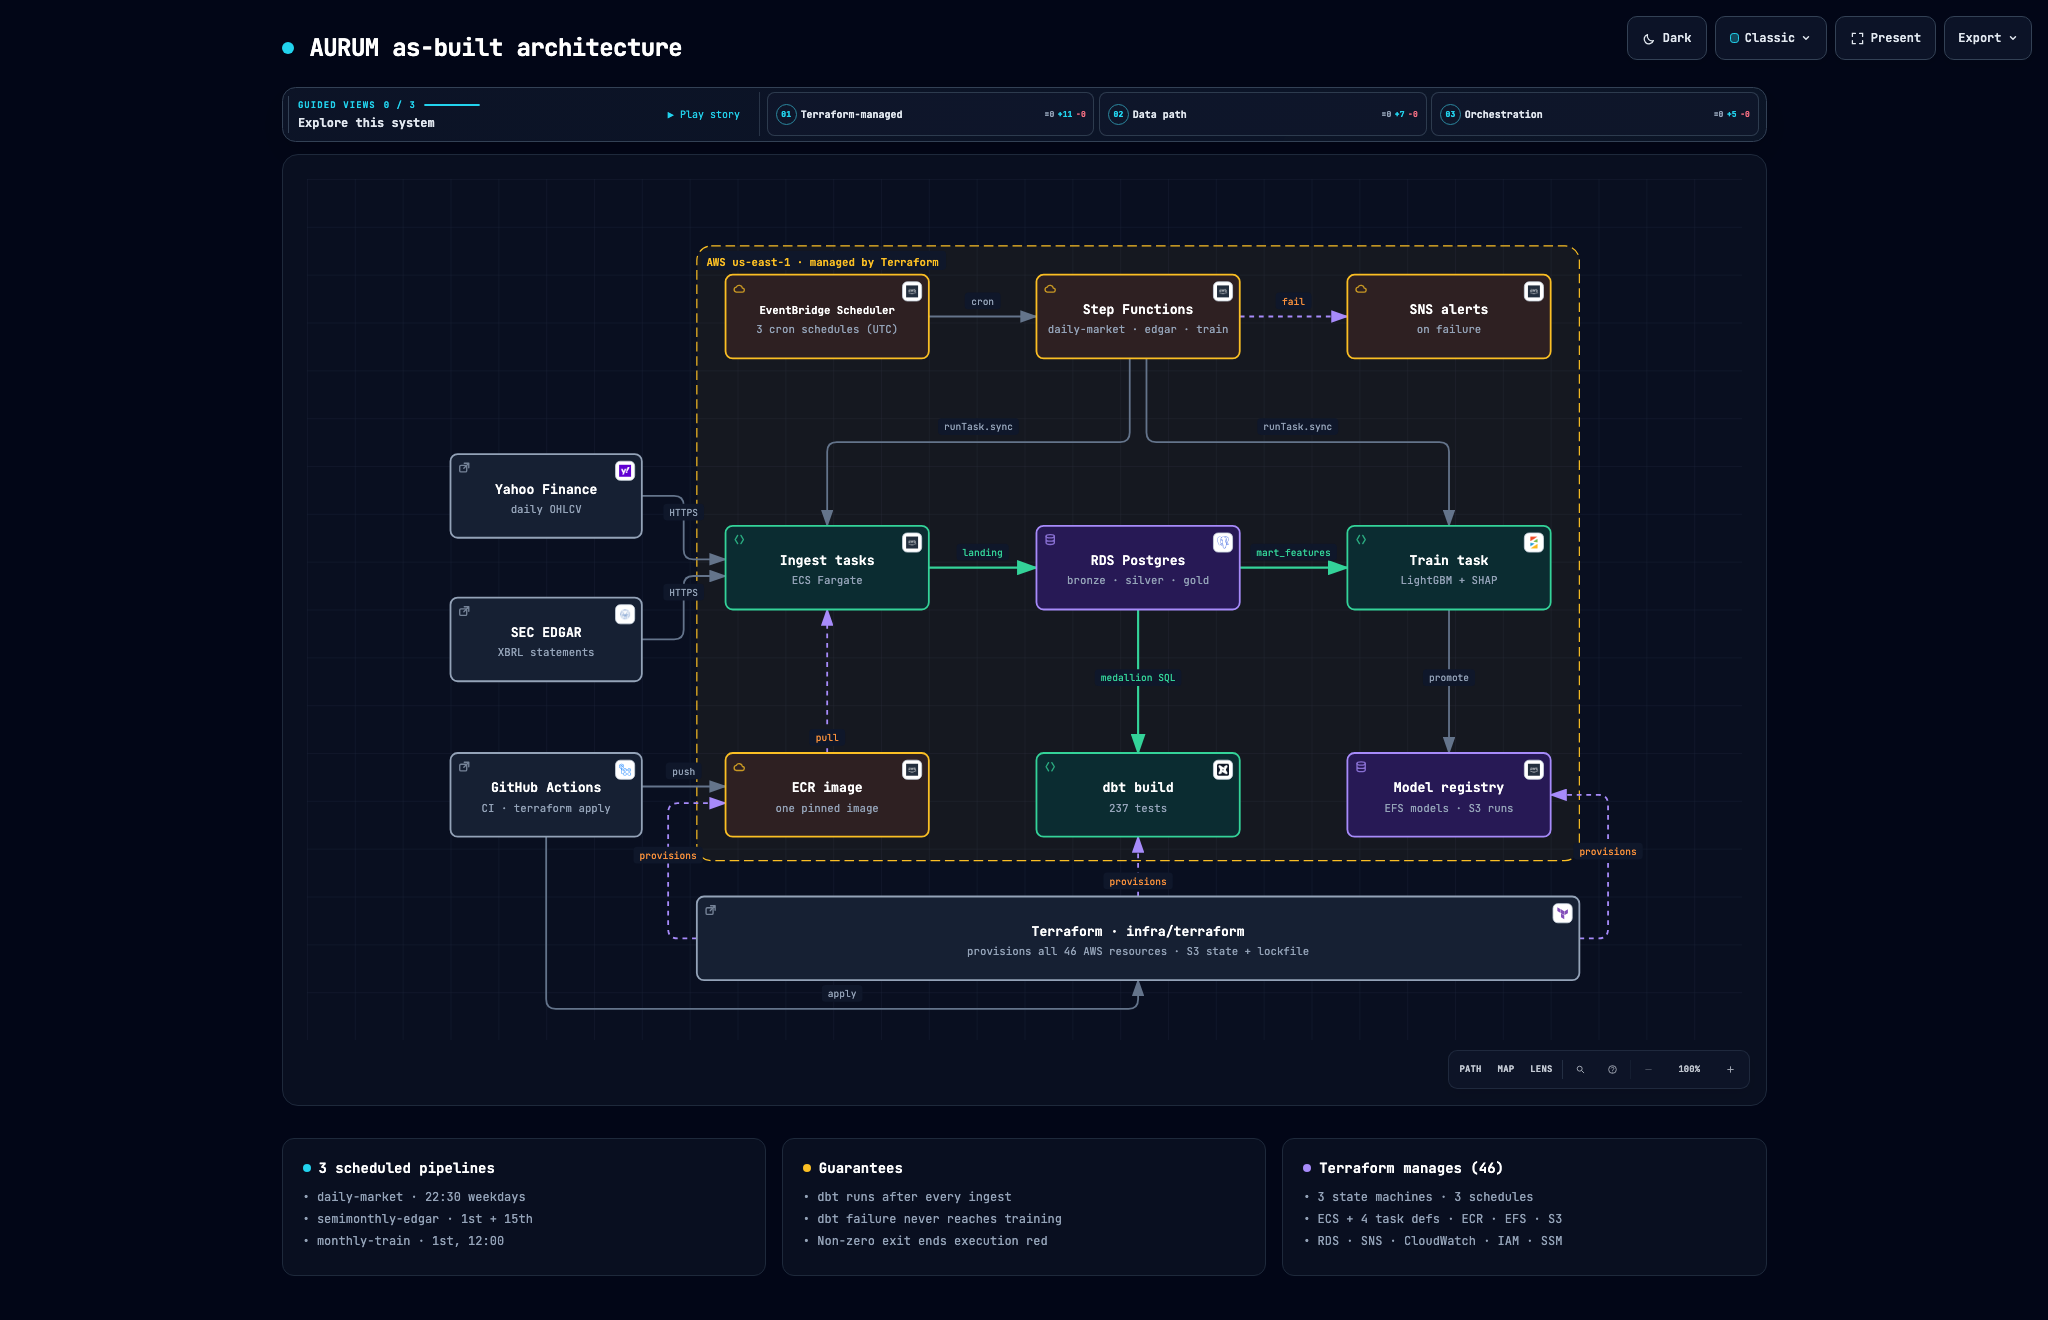
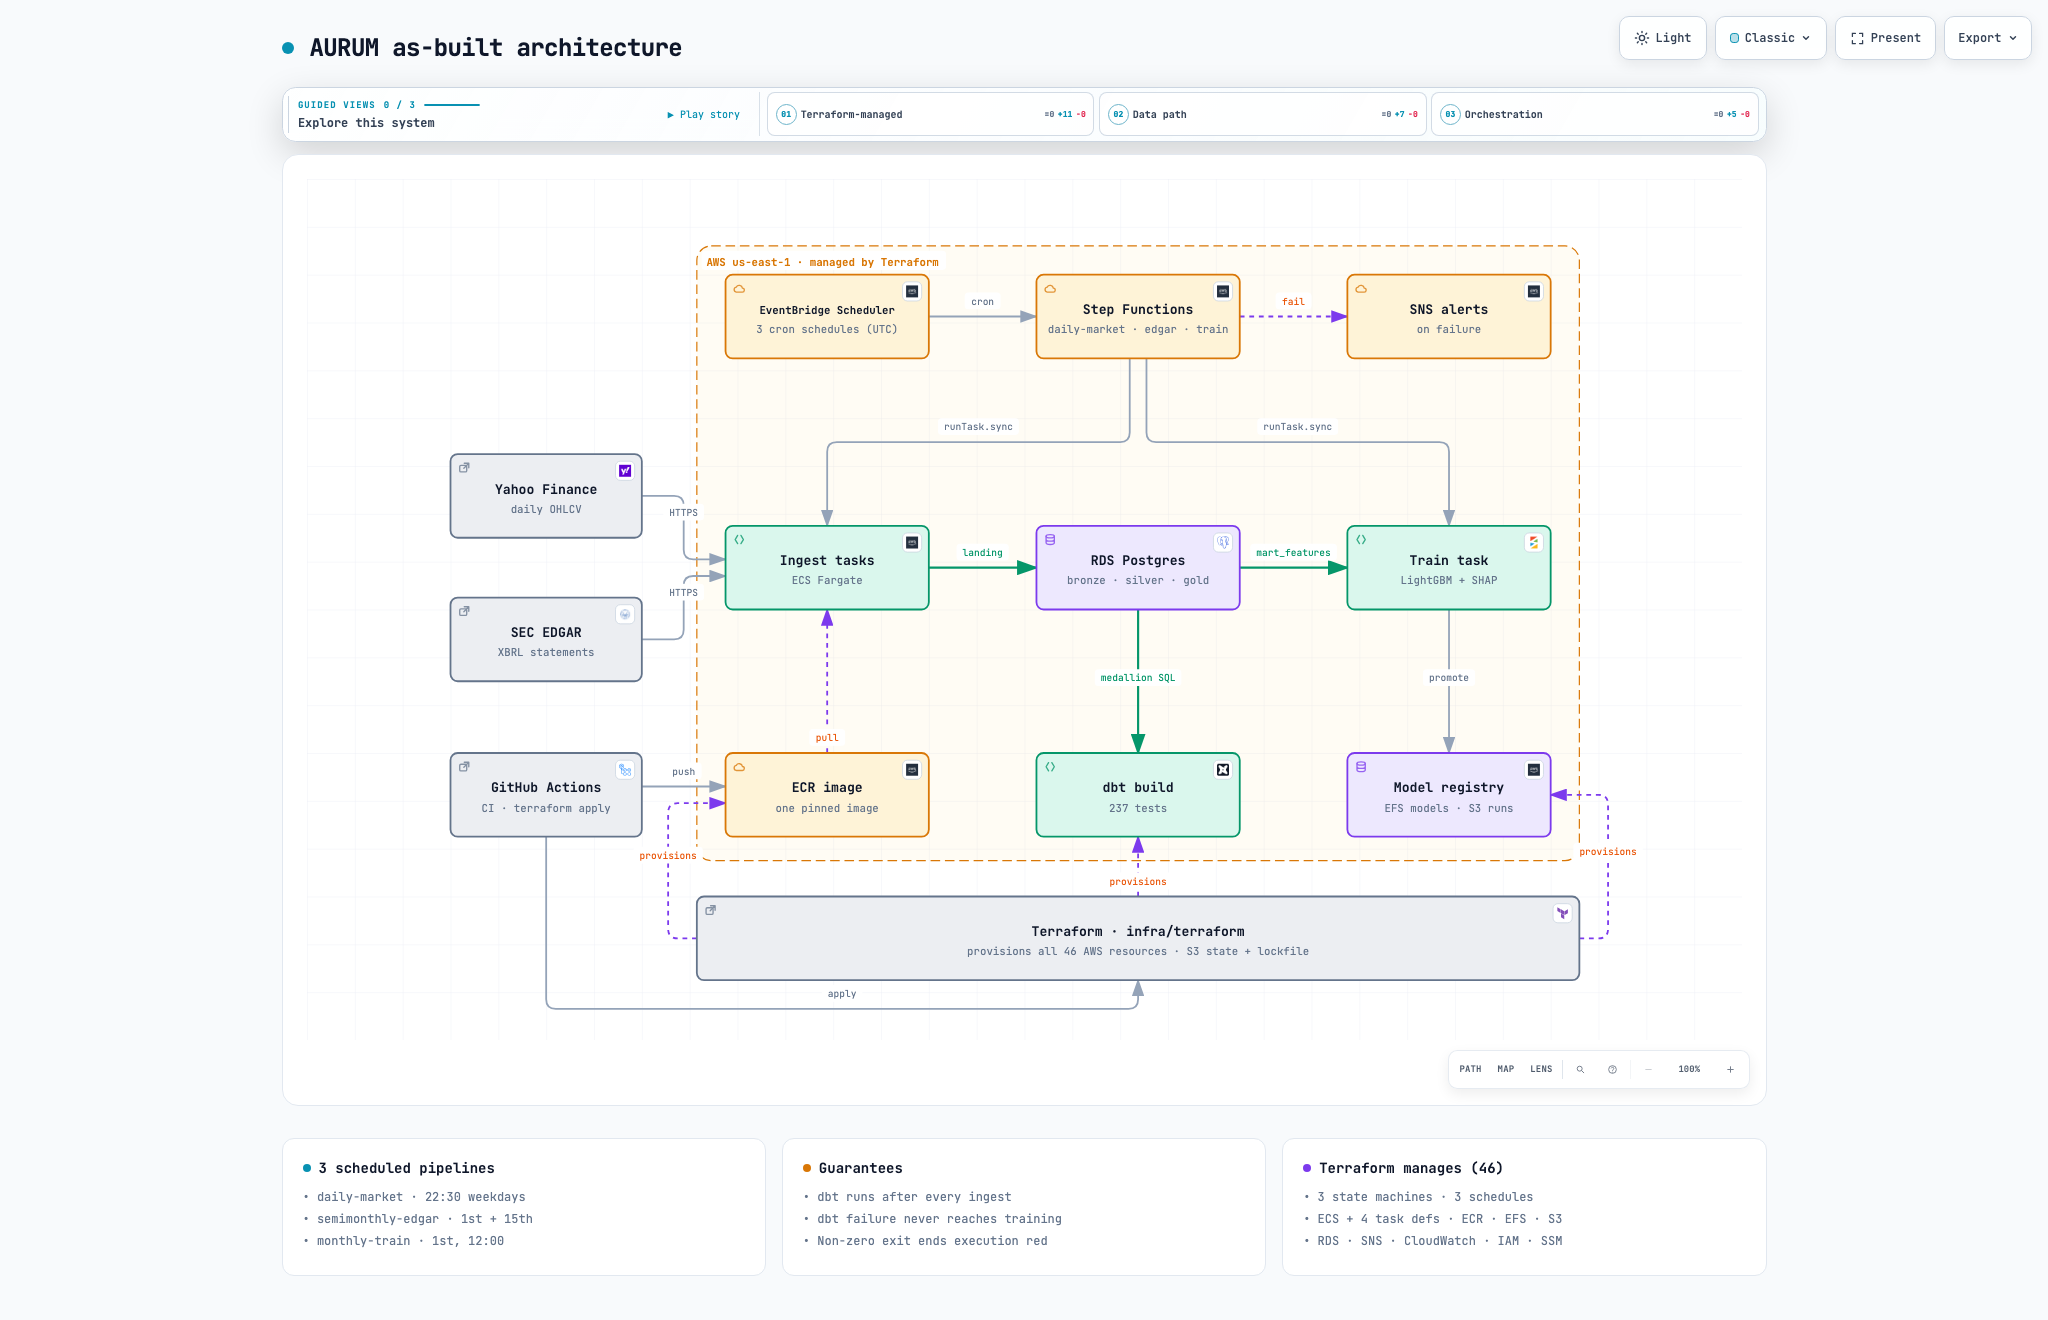
02/How it works
Four layers, each with a job.
stage 01
Ingestion
- 01Config-driven framework: a new source is one YAML file plus one class, registered by decorator.
- 02Incremental loads by watermark with deterministic MD5 row keys — reruns are idempotent.
- 03Chunked, memory-bounded streaming reads; a staleness gate skips EDGAR when data is fresh.
- 04Sources: Yahoo Finance daily prices and SEC EDGAR financial statements.
03/Engineering decisions
What I optimised for.
01
Tests before models
237 data tests run on every build so bad data is caught upstream, not discovered in a backtest.
02
Structural safety
Training is a separate state machine step that only runs after a green dbt build — not a convention, a constraint.
03
Honest evaluation
Holdout data is kept apart from model selection, and backtests include anti-overfitting checks. The model is early-stage; the platform around it is built properly.
04
Free & portable
Every data source is free and nothing is vendor-locked — the whole platform is reproducible from the repo.
04/Stack
Built with.
See it run.
A 40-second walkthrough of the whole system, one continuous shot.